 NexGPU-算力租赁,GPU服务器,GPU云算力,AI服务器租用-新闻博客
A single A100 80GB cannot fit Llama 3 70B FP16 weights, requiring multi-GPU deployment; however, after 4-bit quantization, 8 A100 GPUs can handle private inference of DeepSeek-R1. Evaluating the value of A100 rental requires distinguishing between "fits in memory" and "runs fast," separately accounting for VRAM capacity and data transfer speed.
A100 80GB Memory Allocation and Bandwidth Constraints
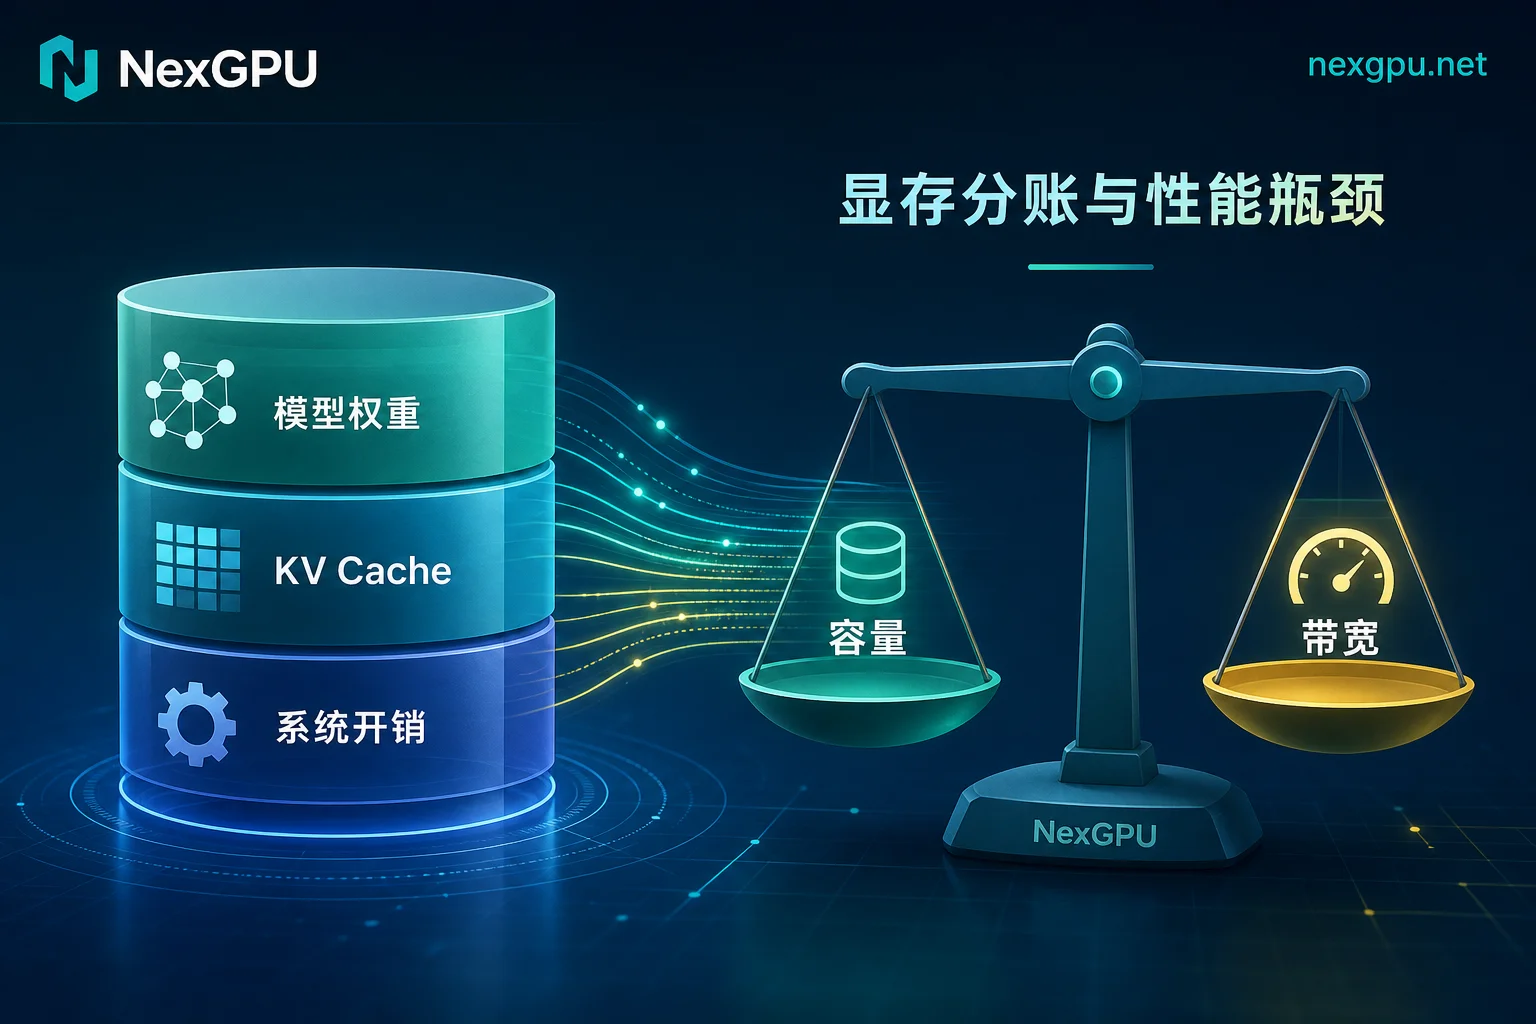
Not all of the 80GB of VRAM on a single GPU is available for weights; it must be divided into model weights, KV cache, runtime, and inference engine overhead. For example, Llama 3 70B in FP16 precision requires about 140GB of weights, which clearly cannot fit on a single 80GB card, necessitating Tensor Parallelism (TP=2) to split across two GPUs. At this point, the bottleneck is not just compute but the latency introduced by inter-GPU communication.
The capacity limit determines whether the model "fits," while the bandwidth limit determines the speed of data movement for each token during the decode phase. Insufficient KV cache headroom forces a reduction in concurrency and context length, leading to low GPU utilization. Therefore, to determine whether larger VRAM is needed, first check if the remaining space can support expected peak business loads.
Placement of a Quantized 671B Model: The Edge of 8-Card A100
For a MoE model like DeepSeek-R1 with 671B total parameters (37B active per token), FP8 precision requires approximately 685GB of VRAM for weights and MTP modules, typically needing 8×H200 or 16 80GB GPUs to run at full capacity. However, after 4-bit quantization such as AWQ/INT4 4-bit quantization, the weight footprint drops to about 335-400GB. This compression makes a single node with 8×A100 80GB (total 640GB) a feasible private inference configuration.
But note, after subtracting weights from 640GB, the remaining space must accommodate KV cache, communication buffers, and runtime overhead. The amount of headroom directly determines the achievable concurrency and maximum context window. If headroom is tight, even if theoretical parameters are met, actual service quality will degrade due to request queuing, block eviction or recomputation, and reduced concurrency and maximum context.
A100, H100, and H200 VRAM Capacity and Placement Comparison
Before debating whether the cost difference between A100 and H100 rental is worth it, it's important to note that both are constrained by the 80GB capacity limit for 70B FP16 scenarios, both requiring TP=2. The real difference lies in the H200's upgraded memory capacity and bandwidth. According to NVIDIA, the H200 uses the Hopper architecture GH100 chip, with compute units and dense FP8 performance (1,979 TFLOPS) identical to the H100. The H200's advantage is its 141GB HBM3e memory and 4.8TB/s bandwidth, offering 76% more capacity and 1.4x bandwidth over the H100's 80GB HBM3.
| Metric | A100 80GB | H100 80GB | H200 141GB |
|---|---|---|---|
| Single GPU memory capacity | 80 GB | 80 GB | 141 GB |
| Can it hold 70B FP16 weights? | No (requires TP=2) | No (requires TP=2) | Yes (single GPU) |
| Number of GPUs for 671B 4-bit weights | 8 GPUs | 8 GPUs | 4 GPUs |
| Impact of inter-GPU communication | High (TP=2) | High (TP=2) | Low (single GPU) |
This means running 70B FP16 on an H200 eliminates the communication latency of tensor parallelism across GPUs. Within the same generation, the extra rent buys not faster computation but larger resident memory and smoother data transfer capabilities.
Converting to Per-Million-Token Cost for Hourly Rental
To accurately assess the economics of A100 rental, you can't just look at the hourly rental price; you must establish a per-million-token cost calculation:
Per-million-token cost = (Number of GPUs × Hourly rental per GPU ÷ Actual tokens output per hour) × 1,000,000
The denominator, "actual tokens output per hour," must come from real load testing, not theoretical compute specs. Before conversion, collect the following variables: number of GPUs and parallelism method, average input/output length, concurrency, prefill and decode throughput separately, peak VRAM usage, and actual utilization including queuing and idle time.
A special reminder: with TP=2, doubling the number of GPUs does not double throughput because the communication overhead of tensor parallelism primarily impacts the token-by-token decode phase. Therefore, conversion must be based on the entire machine's hourly output. Before running the numbers, it's advisable to run a real load test on the target GPU type. If you need to flexibly switch GPU types for comparison testing, you can use NexGPU's pay-as-you-go billing and multi-GPU model selection to quickly complete this benchmark, avoiding locking in long-term resources without real measurement data.
Load-Based Recommendations: Keep Renting A100 or Switch to Larger Memory GPUs
Different scenarios have vastly different memory requirements. The following recommendations, based on typical loads, help you decide between A100 and larger memory GPUs.
| Typical Load Scenario | Recommended Solution | Core Criterion |
|---|---|---|
| Online service for models ≤32B with low-to-medium concurrency | Keep renting A100 (single or multiple GPUs) | Weights don't require cross-GPU slicing; sufficient KV cache headroom |
| 70B FP16 with long context and high concurrency | Switch to H200 or multi-GPU A100/H100 | Single GPU can't fit; cross-GPU communication becomes major bottleneck |
| 4-bit private inference of 671B MoE | 8×A100 or 4×H200 | After 4-bit quantization, weights fit in a single node |
| Short-context tasks primarily for offline batch processing | Keep renting A100 | Insensitive to first-token latency; prioritize throughput |
| Low-priority tasks willing to trade throughput for cost | Keep renting A100 | Allow higher latency; pursue lowest unit cost |
For users who want to understand DeepSeek-R1 private deployment GPU configuration, when you find that cross-GPU communication during the decode phase becomes the main bottleneck, or KV cache headroom severely limits concurrency, it's a signal to consider upgrading from A100 to a larger memory GPU like H200. Additionally, the Qwen2.5-72B multi-GPU quantization deployment tutorial provides a similar topology reference.
Common Questions
Is an A100 80GB enough for 70B inference?
No, a single A100 80GB is not enough. Llama 3 70B FP16 weights are about 140GB, exceeding single-card capacity, so you must use TP=2 to split across two GPUs. While two GPUs solve the capacity issue, they introduce inter-GPU communication latency that affects decoding speed.
Can an A100 80G run a quantized 671B model?
A single card cannot contain it, and half a server (4 cards) is also insufficient. After 4-bit quantization, DeepSeek-R1's weights are about 335-400GB; typically, 8 A100 80GB GPUs are recommended. The minimum number of GPUs cannot be simply calculated by dividing weights by single-card capacity; you must reserve headroom for KV cache and runtime overhead.
In high-concurrency scenarios, is the price difference between A100 and H100 worth it?
Both have 80GB memory, so 70B FP16 requires TP=2 on both; the capacity limit doesn't solve the problem. As for bandwidth and compute differences, since official specs are not publicly verifiable, we can't draw conclusions. It's best to run a real load test on both using the per-million-token calculation method described in this article.
How do I calculate per-million-token cost for pay-as-you-go A100 rental?
The formula is: (Number of GPUs × Hourly rental per GPU ÷ Actual tokens output per hour) × 1,000,000. The key is that the denominator must be the actual hourly output under real load, not theoretical peak. Record peak VRAM usage, concurrency, and separate prefill/decode throughput.
In long-context scenarios, when should I switch from A100 to H200?
When two signals appear: first, 70B FP16 models suffer high decode latency due to TP=2; second, KV cache frequently overflows in long-context or high-concurrency scenarios. In such cases, the H200's 141GB large capacity can eliminate cross-GPU communication and improve effective utilization.
Before making a GPU type decision, run a real load test as described, recording peak VRAM usage, whole-machine hourly token output, and actual utilization; if you need to compare different GPU types under the same load, you can use NexGPU's pay-as-you-go resources for a short comparative test before deciding whether to upgrade.




Comments(0)