 NexGPU-算力租赁,GPU服务器,GPU云算力,AI服务器租用-新闻博客
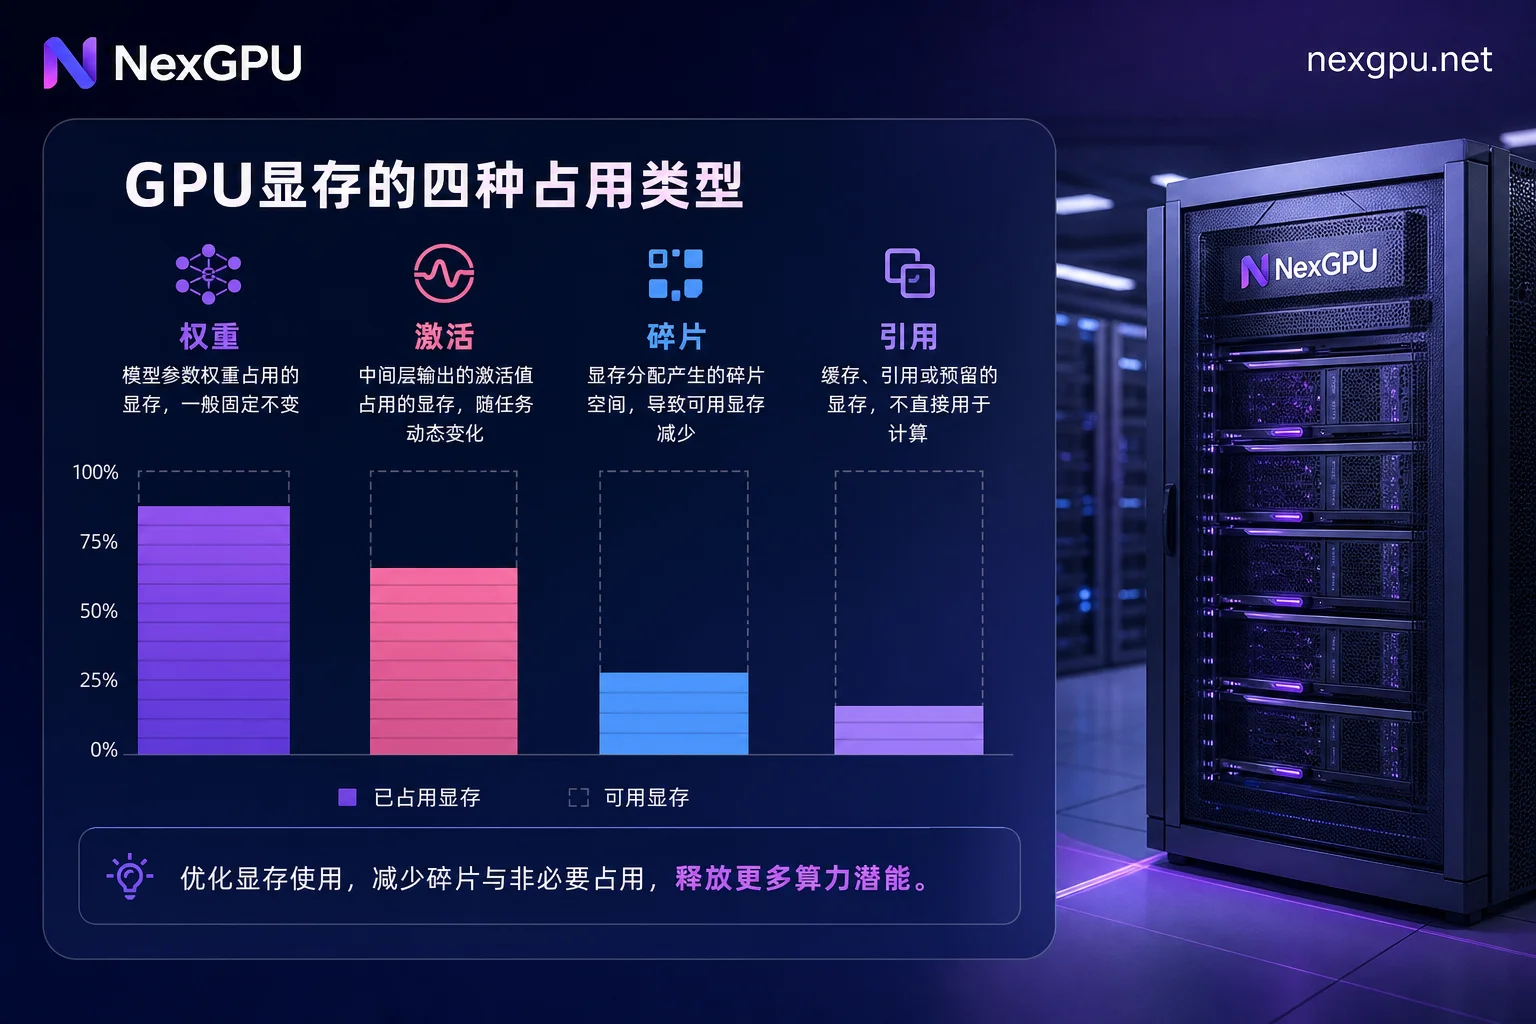
The key to solving GPU Out of Memory is not simply reducing batch size, but first categorizing memory usage into four types—model weights and optimizer states, forward activation peaks, Caching Allocator fragmentation, and Python reference cycle residue—and then using PyTorch's official Memory Snapshot for diagnosis and targeted solutions. PyTorch's official (December 2023 series of technical blogs) has upgraded troubleshooting from "reduce batch size / clear cache" to categorical diagnosis. This article follows that path in five steps, covering common scenarios where OOM occurs at the first step of training a 7B model.
First, Distinguish Four Types of OOM: Weights, Activation Peaks, Allocator Fragmentation, and Unreleased References
Before taking action, classify the issue; otherwise, you'll only be guessing. GPU memory mainly consists of four types, each with completely different symptoms and solutions:
- Model Weights and Optimizer States: Resident memory, fixed amount. If OOM occurs on the first step and the allocator reports total allocated memory close to the card's capacity, it's likely this type.
- Forward Activation Peaks: Grow linearly or super-linearly with batch size and sequence length. Typical manifestation: training continues after reducing batch size, but OOM returns when restoring original value.
- Caching Allocator Fragmentation: PyTorch's memory allocator may request memory from the driver, but internal fragmentation leads to insufficient effective space. Typical symptom: "CUDA out of memory" but there's still free memory; Reserved is much larger than Allocated.
- Python Reference Cycle Residue: Tensors that should be released are retained due to reference cycles. Typical symptom: OOM occurs halfway through training, and memory usage shows a jagged or step-like climb.
Step 1: CUDA Out of Memory But Still Has Free Memory? First Read allocated / reserved / free
Three numbers in PyTorch error messages: Allocated is the actual usage of active tensors, Reserved is the total amount requested by the caching allocator from the CUDA driver, and Free is the physical remainder. The judgment is simple:
| Scenario | Symptom | Conclusion |
|---|---|---|
| Reserved much larger than Allocated | OOM but memory still free | Points to fragmentation |
| Allocated close to Reserved | Close to card's physical memory | Real capacity shortage |
Let's correct a common misconception: torch.cuda.empty_cache() only returns unused reserved memory blocks to the driver, doesn't release active tensors, and won't raise the physical limit; frequent calls also bring synchronization overhead and reduce throughput. For details, see PyTorch CUDA Semantics Documentation.
Step 2: Use PyTorch Memory Snapshot to Record Allocation Stacks and Generate Memory Timeline
PyTorch's official Memory Snapshot can capture the full lifecycle of allocation/deallocation stacks and visualize them with microsecond-level timeline. The official blog provides detailed instructions. Usage is as follows:
import torch
torch.cuda.memory._record_memory_history()
# 运行你的训练或推理代码
torch.cuda.memory._dump_snapshot("snapshot.pickle")
torch.cuda.memory._record_memory_history(enabled=None)
Then drag the generated .pickle file into the official visualization tool https://pytorch.org/memory_viz to view the memory timeline and call stacks at each allocation point. The whole process relies only on official APIs; avoid undocumented parameters.
Step 3: How to Locate Memory Leaks—Read Peaks and Climbs from Timeline Patterns
Read the conclusion from the timeline pattern:
- Single spike: Points to an activation peak from a certain operator or backward pass; check the call stack at the spike moment.
- Jagged or step-like persistent climb: Points to retention due to reference cycles; call stack will show tensors not being released.
- Flat high level: Resident weights and optimizer states, almost unchanged.
After locating the specific code position, decide next actions. If the timeline shows stable memory but low throughput, the issue may be on the compute side rather than memory side; refer to GPU Utilization Optimization.
Step 4: Apply Targeted Solutions—Gradient Checkpointing, Precision Tuning, Allocator Parameters, Break Reference Cycles
The GPU Out of Memory solution comes down to actions here: four root causes correspond to four types of solutions.
- High activation peak: Use gradient checkpointing, discard intermediate activations in forward pass and recompute in backward, trading about 20% compute time for significant activation memory reduction.
- Fragmentation: Configure
PYTORCH_CUDA_ALLOC_CONF=expandable_segments:True(in newer versionsPYTORCH_ALLOC_CONF), using CUDA VMM to dynamically extend memory segments, eliminating segment fragmentation. - Reference cycles: Locate the object from the call stack, use
delto explicitly delete or refactor code to break references. - Resident weights: Weights and optimizer states stay in memory; can be compressed by lowering precision, switching to more memory-efficient optimizer implementations, or sharding strategies; different solutions have different effects on weights, gradients, and optimizer states, so need to calculate based on the resident usage in the actual error.
Note that expandable_segments cannot break the physical memory hard limit and cannot completely eliminate OOM.
Step 5: Confirm Whether a Larger GPU is Really Needed—Use the Same Script for Peak Comparison
If Allocated still approaches physical memory after the above measures, the code side has done its best. At this point, you can temporarily switch to a larger GPU using on-demand GPU resources, run the same script to compare memory peaks, and use the two data sets to determine whether it's a code or card issue. For example, NexGPU provides on-demand instances, allowing you to verify without long-term card ownership, avoiding blind upgrades. See How to Choose GPU Memory for capacity differences across cards.
Special Case on the Inference Side: KV Cache and Memory Utilization Parameters
Inference memory composition differs from training: KV Cache grows with concurrency and context length, becoming the main memory variable. An NVIDIA official (September 2025) article points out that CPU-GPU memory sharing and KV Cache offloading are directions the industry is pursuing, but specific gains vary by hardware and framework; no numbers are given here. Also, the inference framework's memory reservation ratio parameter interacts with PyTorch allocator behavior; before tuning, consider the framework's reservation parameters together with expandable_segments. For related practices, refer to vLLM Multi-GPU Tensor Parallel Configuration Guide. When estimating model memory requirements, refer to How Much Memory Does Qwen Deployment Need.
Troubleshooting Checklist and Four Common Misjudgments
Condense the above GPU Out of Memory solution into an executable checklist.
- [ ] Record Allocated and Reserved on error to judge fragmentation.
- [ ] Enable Memory Snapshot, capture call stacks and timeline.
- [ ] Locate the peak or climb position and code.
- [ ] Apply targeted solutions: gradient checkpointing, expandable_segments, break reference cycles.
- [ ] If still OOM after treatment, use a larger card for peak comparison.
Four common misjudgments:
- Thinking
empty_cache()can expand memory—it only releases idle blocks. - Thinking enabling
expandable_segmentsnever OOM—physical limit still exists. - Treating fragmentation as insufficient card—first look at the gap between Reserved and Allocated.
- Treating slow climbs from reference cycles as normal growth—note jagged patterns.
FAQ
CUDA out of memory but still has free memory—why?
Most likely Caching Allocator fragmentation. Reserved has allocated large memory chunks, but internal blocks cannot satisfy new requests. Solution: enable expandable_segments:True, or restart the process to release fragmentation, and observe if it improves.
OOM halfway through training—what's the cause?
Usually memory leak due to reference cycles. Python's cyclic GC can only reclaim passively. Recommend enabling Memory Snapshot to capture call stacks during the climbing segment to locate unreleased tensors.
How to use PyTorch memory snapshot?
Use torch.cuda.memory._record_memory_history() to enable recording, export the snapshot at runtime, then load it in the official memory_viz page to view allocation timeline and call stacks.
How to locate memory leaks?
The most direct way is to generate two Memory Snapshots spaced a few steps apart, compare the call stacks of unreleased tensors, and find the reference cycles.
Is PYTORCH_CUDA_ALLOC_CONF expandable_segments useful?
Yes, but it only solves fragmentation. It uses VMM to dynamically extend memory segments, reducing segment fragmentation, but when weights or activations exceed physical capacity, OOM still occurs; it's not a universal switch.
The above is the complete closed loop of GPU Out of Memory solutions. First run the checklist to complete Memory Snapshot troubleshooting, confirm the bottleneck category, then decide whether to modify code or change card type; for card comparison, use NexGPU on-demand resources for short-term validation, avoiding long-term upgrades.




Comments(0)