 NexGPU-算力租赁,GPU服务器,GPU云算力,AI服务器租用-新闻博客
In the evolution of AI technology, we often hear developers facing this dilemma: from running models on a single GPU in a personal lab to large-scale distributed training and inference in enterprises, there seems to be an insurmountable computing power gap.
When your AI business moves from prototype to production, a single consumer-grade GPU is no longer sufficient to handle high-concurrency requests and massive model fine-tuning parameters. At this point, building a GPU cluster is not just about stacking hardware, but a comprehensive test of elasticity, efficiency, and cost control.
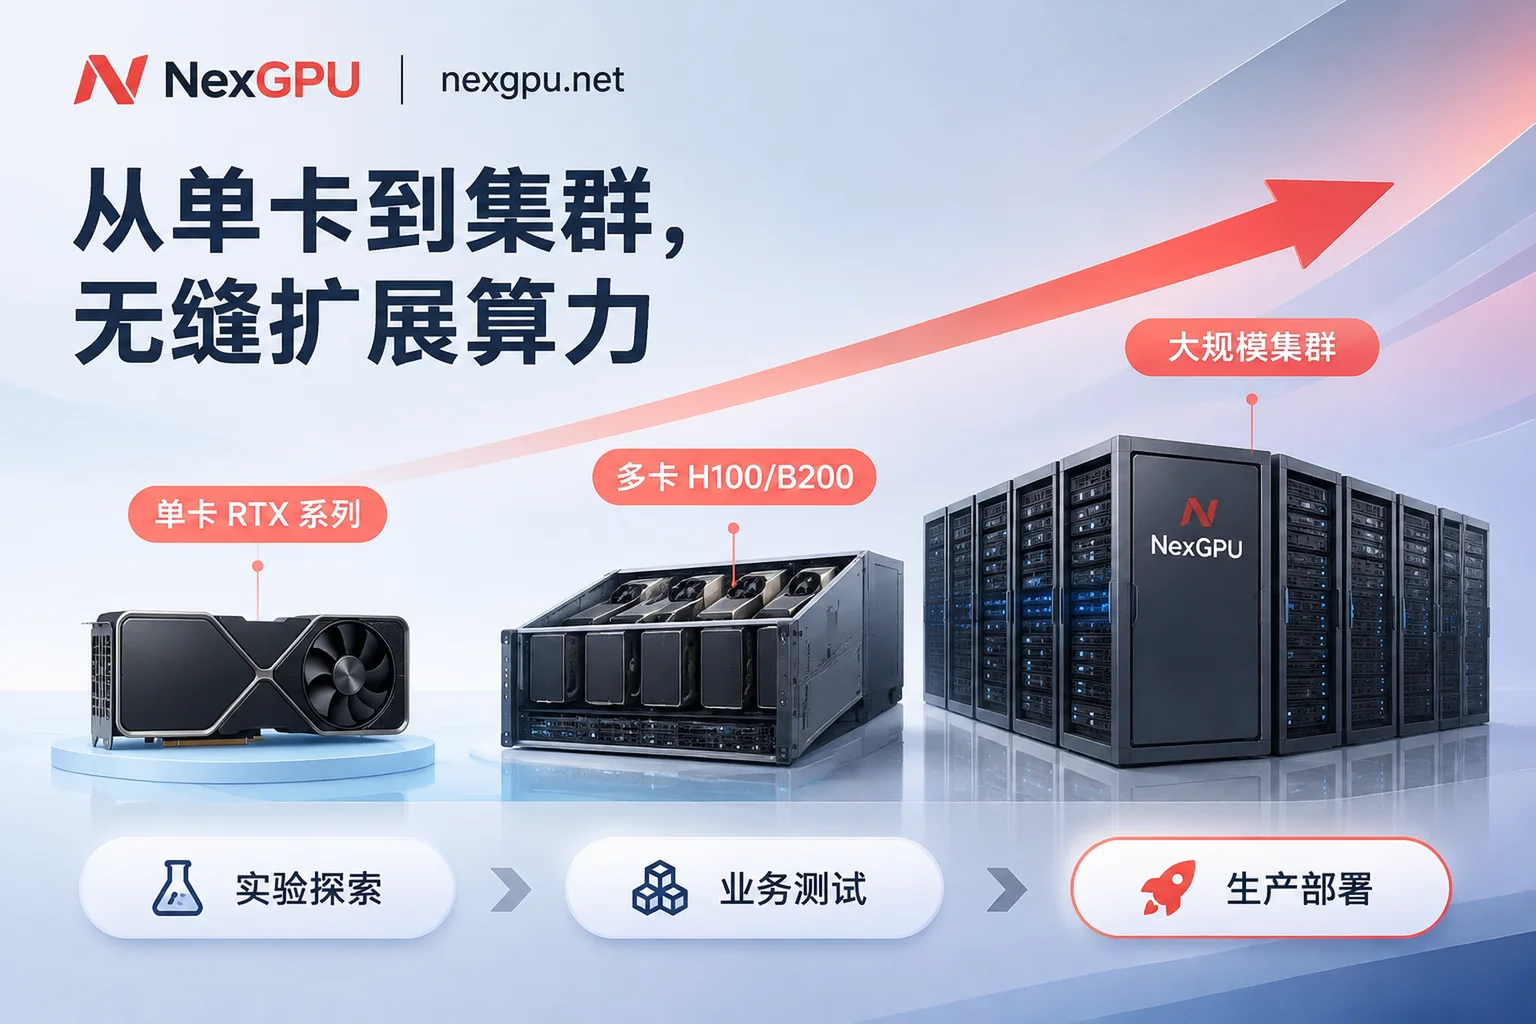
The Key to Transitioning from a Single-Card "Workshop" to a Multi-Card "Factory"
Many teams easily fall into "hardware anxiety" when scaling up, worrying that purchasing expensive A100 or H100 hardware not only has slow delivery but also incurs unbearable costs when idle. The hourly billing model provided by NexGPU GPU marketplace is designed to address this pain point.
By aggregating global distributed computing power, we allow you to directly rent high-performance multi-GPU nodes including H100, H200, and B200 without dealing with tedious server operations. Whether you are accelerating with DeepSpeed or deploying the Megatron framework, you can filter machines with high-speed interconnect capabilities on demand, achieving instant scaling of computing resources according to business fluctuations.
Why Choose NexGPU to Build Your Elastic Cluster?
- Transparent cost calculation: No minimum consumption, billing by the second, fine-grained separation of storage and bandwidth, avoiding hidden costs. For R&D teams, this is not just a bill, but a precise dashboard for evaluating model cost-effectiveness.
- Out-of-the-box pre-configured images: The most time-consuming environment setup for cluster building has been completely solved through our image templates. Whether it's Unsloth/LLaMA Factory commonly used for fine-tuning, or vLLM/SGLang essential for inference, you can get started immediately via web terminal or SSH after booting.
- Flexible scaling logic: In the model selection guide, we detail the VRAM requirements for mainstream models. You can start testing with a single RTX 4090, and when the need for model quantization increases, smoothly scale to a multi-GPU node cluster with minimal code migration cost.
Breaking Through Production-Level Bottlenecks: More Than Just Computing Power
For enterprise-level requirements that need private deployment and high-concurrency inference, in addition to basic computing power, NexGPU also offers customized enterprise solutions. For complex tasks requiring RDMA high-speed interconnect and data isolation, we can assist in building dedicated private computing pools to ensure your core models run efficiently in an isolated and secure environment.
Don't let hardware barriers lock up your AI creativity. Whether exploring multi-GPU distributed training or optimizing large-scale inference pipelines, visit NexGPU to let your computing power reserves grow in sync with your AI business.
Want to learn more about avoiding performance pitfalls? Check out our solutions page to master the optimal computing configuration for different business scenarios.



