 NexGPU-算力租赁,GPU服务器,GPU云算力,AI服务器租用-新闻博客
In the tech landscape of 2026, "GPU clusters" are no longer exclusive to tech giants. Whether you're a startup focused on AI agent development or a visual studio handling large-scale rendering tasks, as your business scales from single-GPU inference to large model training, high-performance fine-tuning, or parallel rendering, building a GPU cluster that is elastic, cost-effective, and low-barrier has become a "must-do" for R&D teams.
Why are developers shifting to elastic clustering?
Recent industry trends show that pursuing extreme single-GPU performance alone can no longer meet complex parallel tasks. Whether using DeepSpeed for distributed model training or Megatron to optimize inference for extremely large models, clustered deployment is an unavoidable threshold.
However, self-built clusters face pain points such as equipment depreciation, high maintenance costs, and inflexible scaling. What developers need is a virtualized cluster solution that is "on-demand, pay-as-you-go, and scalable".
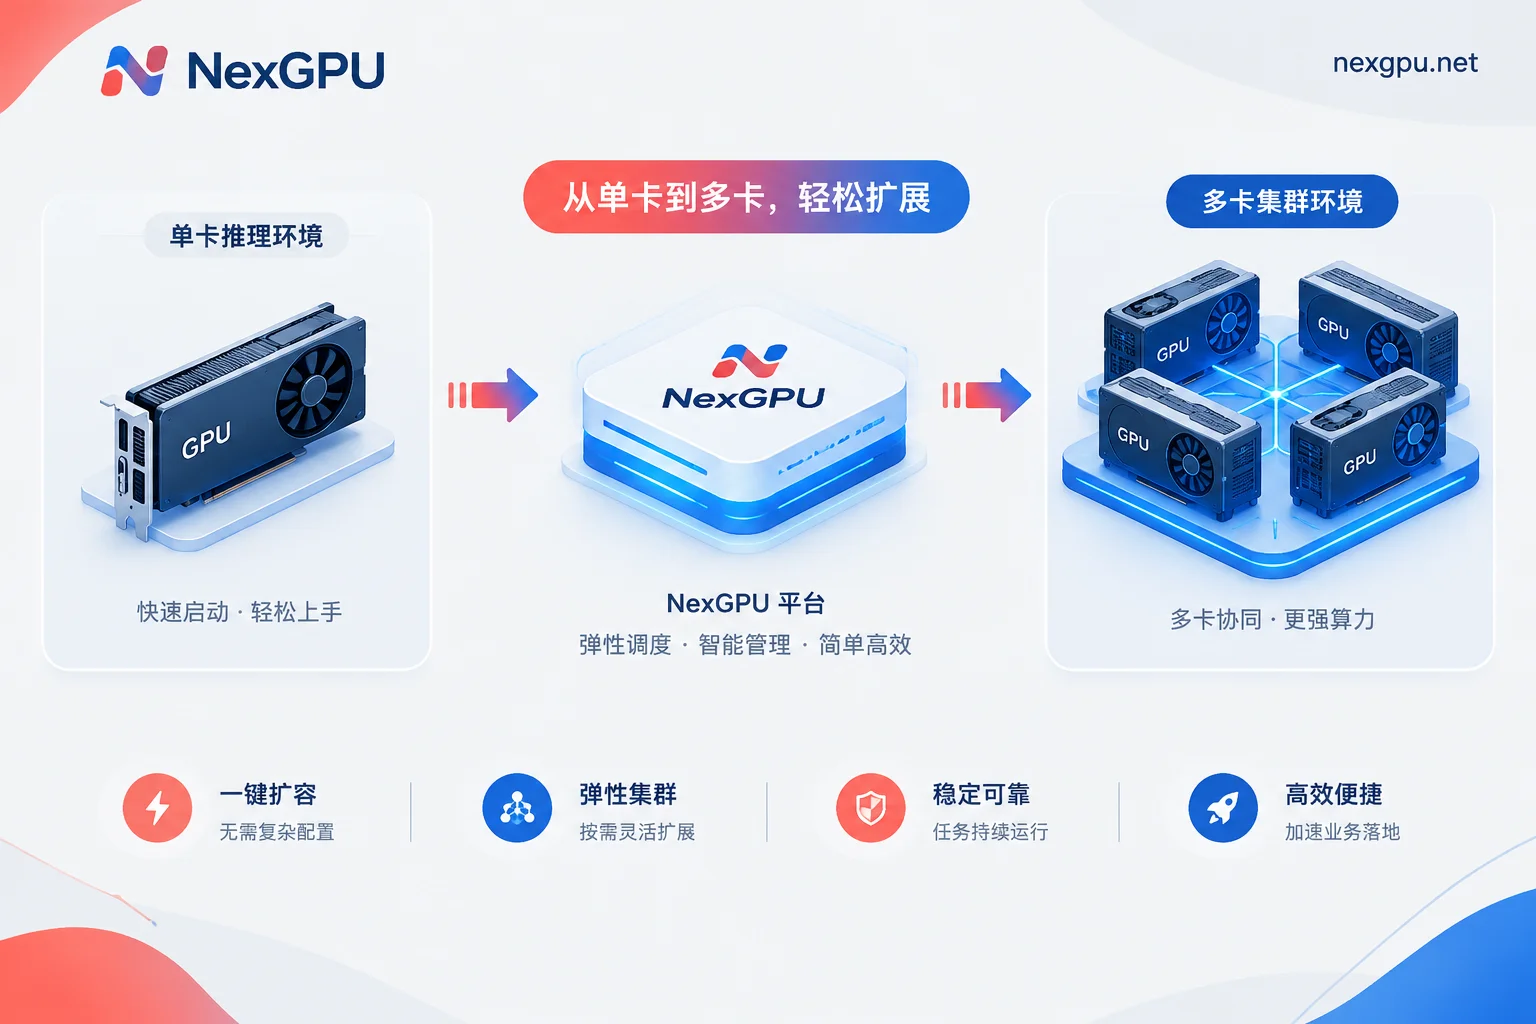
From Single GPU to Cluster: NexGPU's Elastic Evolution Logic
NexGPU aims to eliminate the friction in acquiring computing resources and help developers achieve seamless switching of computing power:
- On-demand GPU selection, seamless scaling: In the GPU Marketplace, you can choose GPUs like picking products. From high-performance consumer-grade cards like RTX 4090/5090 to top-tier data center GPUs like A100, H100, H200, B200, each machine displays its computing unit price in real-time. When you need to scale, simply order on-demand; the system supports whole-machine rental of multi-GPU nodes, easily meeting distributed computing needs.
- Out-of-the-box cluster environment: In the Image Templates, we pre-install mainstream training frameworks including PyTorch and JAX, as well as environments optimized for distributed tasks. Whether you're doing model fine-tuning, inference deployment, or Blender segmented parallel rendering, it's ready to use upon startup, avoiding tedious environment configuration.
- Flexible connection and management: Provide web terminal, direct SSH, and Jupyter environments, making cluster management as intuitive as local development. Through the details page, you can monitor the load of each instance in real-time, stop instances while retaining data, and flexibly control costs.
Enterprise Solutions: Meeting Higher-Level Interconnect Needs
For teams handling extreme performance tasks, NexGPU also offers in-depth support:
If you need RDMA high-speed interconnect, data isolation, or dedicated computing clusters, we support custom enterprise solutions. You can contact sales to reserve instances, purchase monthly/yearly plans, or establish dedicated computing pools to meet the strict stability and network throughput requirements of research or production-grade tasks.
Cost Control: Ultimate Cost-Effectiveness with Per-Second Billing
Abandon expensive prepaid models; NexGPU adopts pure per-second metering and hourly pricing. Bills for computing, storage, and traffic are clear, with no hidden fees and no minimum rental threshold. Let your budget be fully invested in effective computing time.
Want to start your cluster journey?
- Refer to the Model Selection Guide to quickly identify the target GPU based on memory requirements and task types.
- Browse the Scenario Practices Page for optimal architecture recommendations for different business scenarios (e.g., AI fine-tuning, distributed rendering).
No real-name authentication required; register and use immediately. Go to the NexGPU official website now and start your efficient computing journey.



